
 RAG & AI Knowledge Systems for B2B SaaS

01 — EVALUATION
RAG Evaluation Sprint
From $750
A focused review of retrieval quality, evidence coverage and the next engineering decisions.
- Current system review
- Data and workflow constraints
- Architecture recommendation
- Risks
- Implementation roadmap
RAG & AI Knowledge Systems for B2B SaaS
I build production-focused RAG systems, knowledge assistants and document-intelligence workflows with citations, evaluation and tenant-aware access controls.
Most AI features are easy to demo. The hard part is making them trustworthy when the knowledge is private, constantly changing, and split across documents, databases and product surfaces.
I build the retrieval, evaluation and access-control layer that turns that knowledge into answers users can inspect and verify.
ENGINEERING PRINCIPLES
Ground the answer Retrieval should surface relevant evidence, answers should cite it, and the system should have a safe path when evidence is insufficient.
 GROUNDING
Bound the system Models should not decide permissions. Access controls, validation and tenant boundaries belong in deterministic infrastructure.
 SECURITY
Evaluate before rollout Retrieval quality, citation behavior and failure cases should be tested before a workflow becomes production-critical.
 EVALUATION
WAYS TO START
Each engagement starts from the problem and ends with something you can inspect: a decision, a working workflow, or a production system with a handover.
01 — EVALUATION
From $750
A focused review of retrieval quality, evidence coverage and the next engineering decisions.
02 — PILOT
From $2,500
One defined production workflow built and validated against real constraints.
03 — IMPLEMENTATION
Custom scope
A complete knowledge system shaped around your data, integrations, access boundaries and production needs.
Final scope, timeline and pricing are confirmed after a technical review.
Ongoing Engineering Support
Available after delivery.
PROCESS
Four steps. Each one ends with something decided, tested or shipped.
01
Define the workflow, the data, the constraints and what success actually means.
02
Test the retrieval or model approach and the failure modes before building around it.
03
Implement the production workflow and the integrations it depends on.
04
Security, evaluation, observability, deployment, documentation and handover.
ABOUT
I’m Muhammad Daniyal, an independent AI systems engineer focused on RAG and AI knowledge systems for B2B SaaS — retrieval, citations, evaluation and tenant-aware access controls.
More about how I work →DocuMind and LeadCore are products I built as engineering proof. They are my own products, not client deployments.
FAQ
No. Both are my own products, built as engineering proof for the kind of systems I take on. The architecture, trade-offs and limitations described in each case study are my own decisions.
B2B SaaS teams whose product or internal knowledge already exists, and whose AI answers now need to be verifiable, permission-aware and measurable in production.
A defined scope agreed up front: the workflow, the integrations, the evaluation approach and the deployment path. Every engagement ends with documentation and a handover you can maintain.
Custom deliverables and project-specific IP transfer according to the engagement agreement. Third-party and open-source components retain their respective licenses.
Taking new projects. Typical start is 1–2 weeks ahead. If you have a fixed deadline, include it in the brief.
I’m Muhammad Daniyal, an independent AI systems engineer focused on RAG and AI knowledge systems for B2B SaaS.
I work across retrieval, document intelligence, evaluation, tenant isolation and the production infrastructure around AI features — not just the model call.
DocuMind AI and LeadCore AI are products I built as engineering proof. They are my own products, not client deployments.
Focus & Current Work
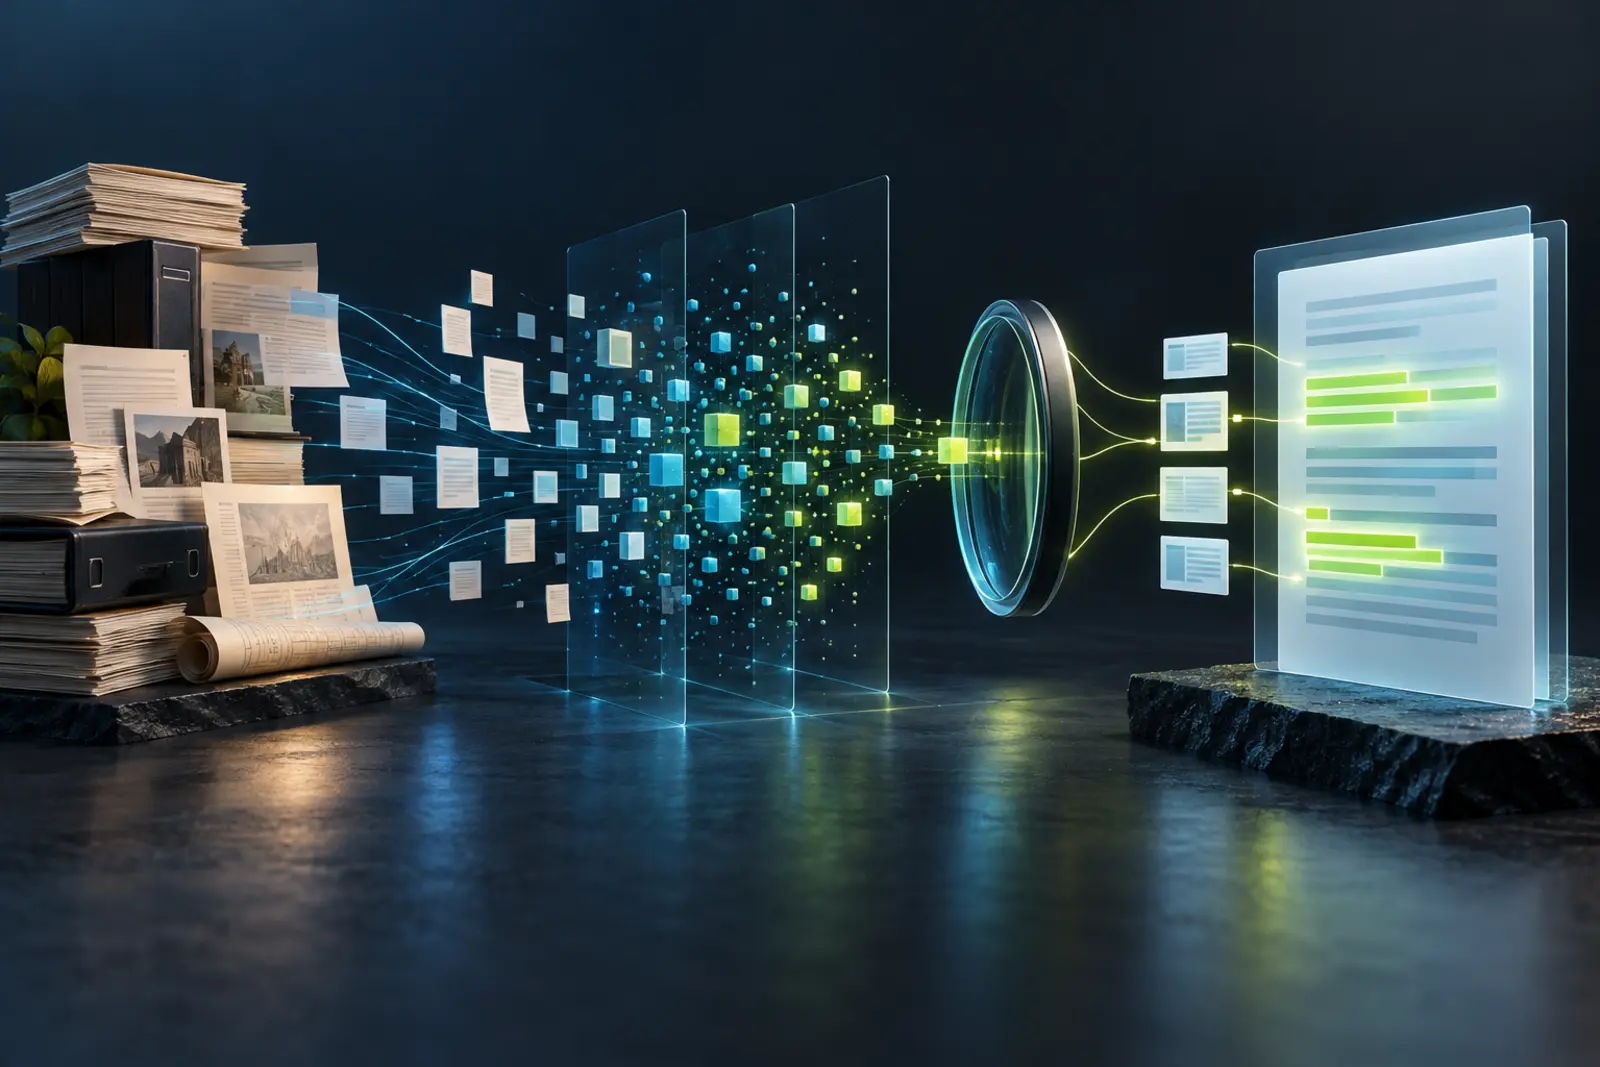
I design and build the production layer beneath AI features: retrieval, document intelligence, evaluation, tenant isolation and the deterministic controls around the model call.
Engineering focus
Trust is in the sources.
– house rule
A production-focused RAG system for knowledge users to verify
Product knowledge is fragmented across files, URLs and documentation that keeps changing. An AI answer is only useful if the reader can check where it came from.
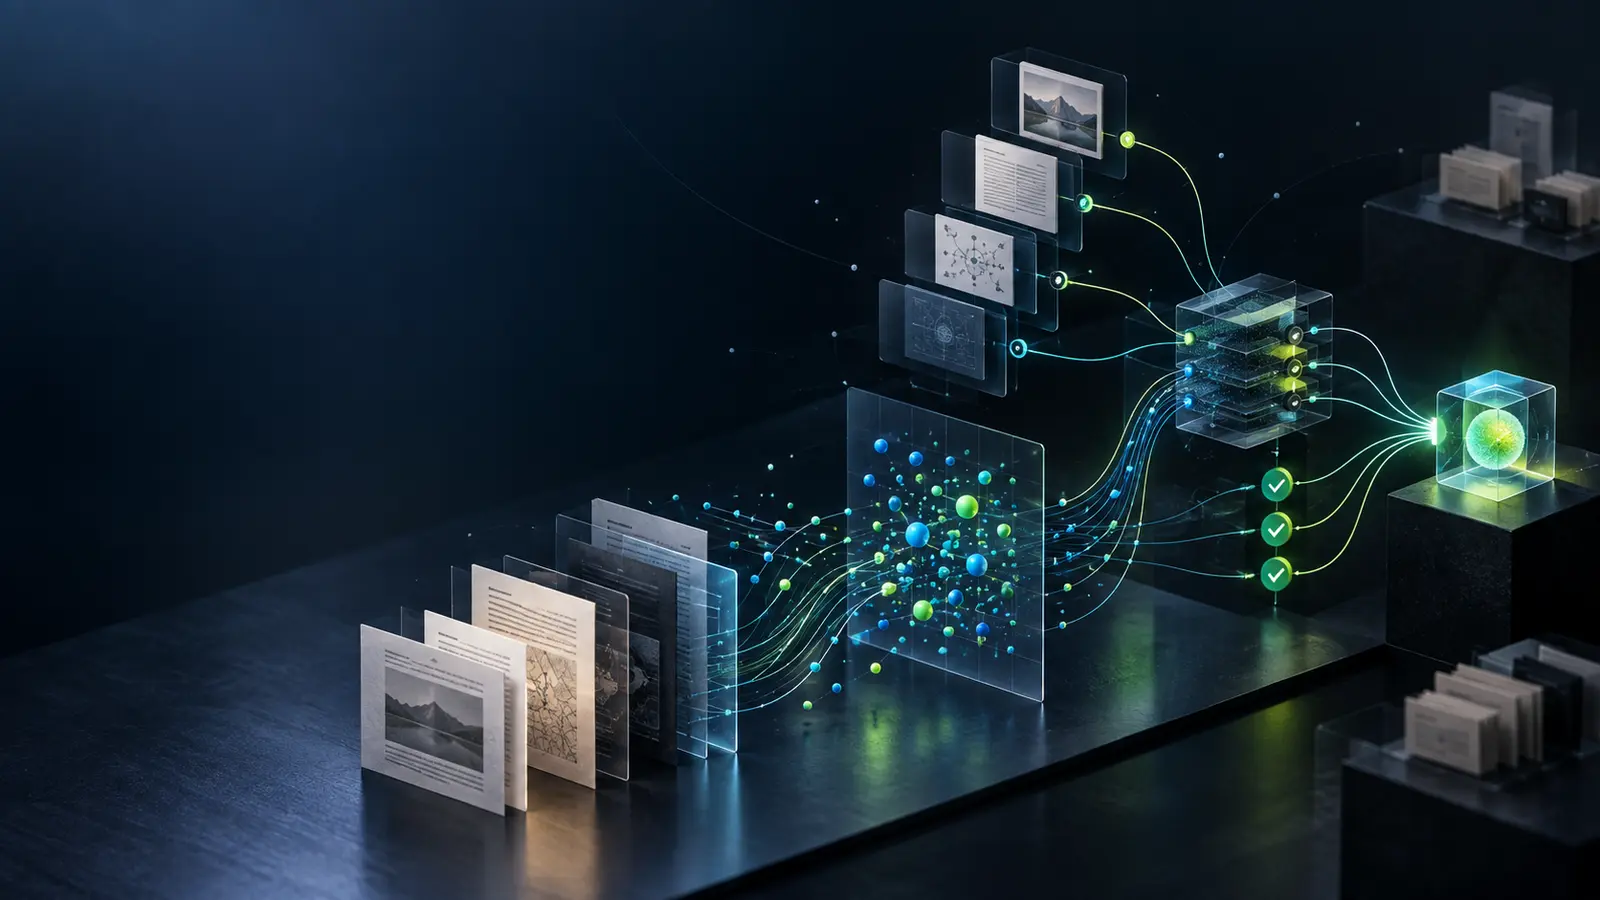
DocuMind AI is a production-focused system I built as engineering proof: ingestion and parsing, similarity retrieval with reranking, grounded answers with inline citations, workspace-scoped access, and evaluation of the parts that decide whether the answer can be trusted. It is my own product, not a client deployment.
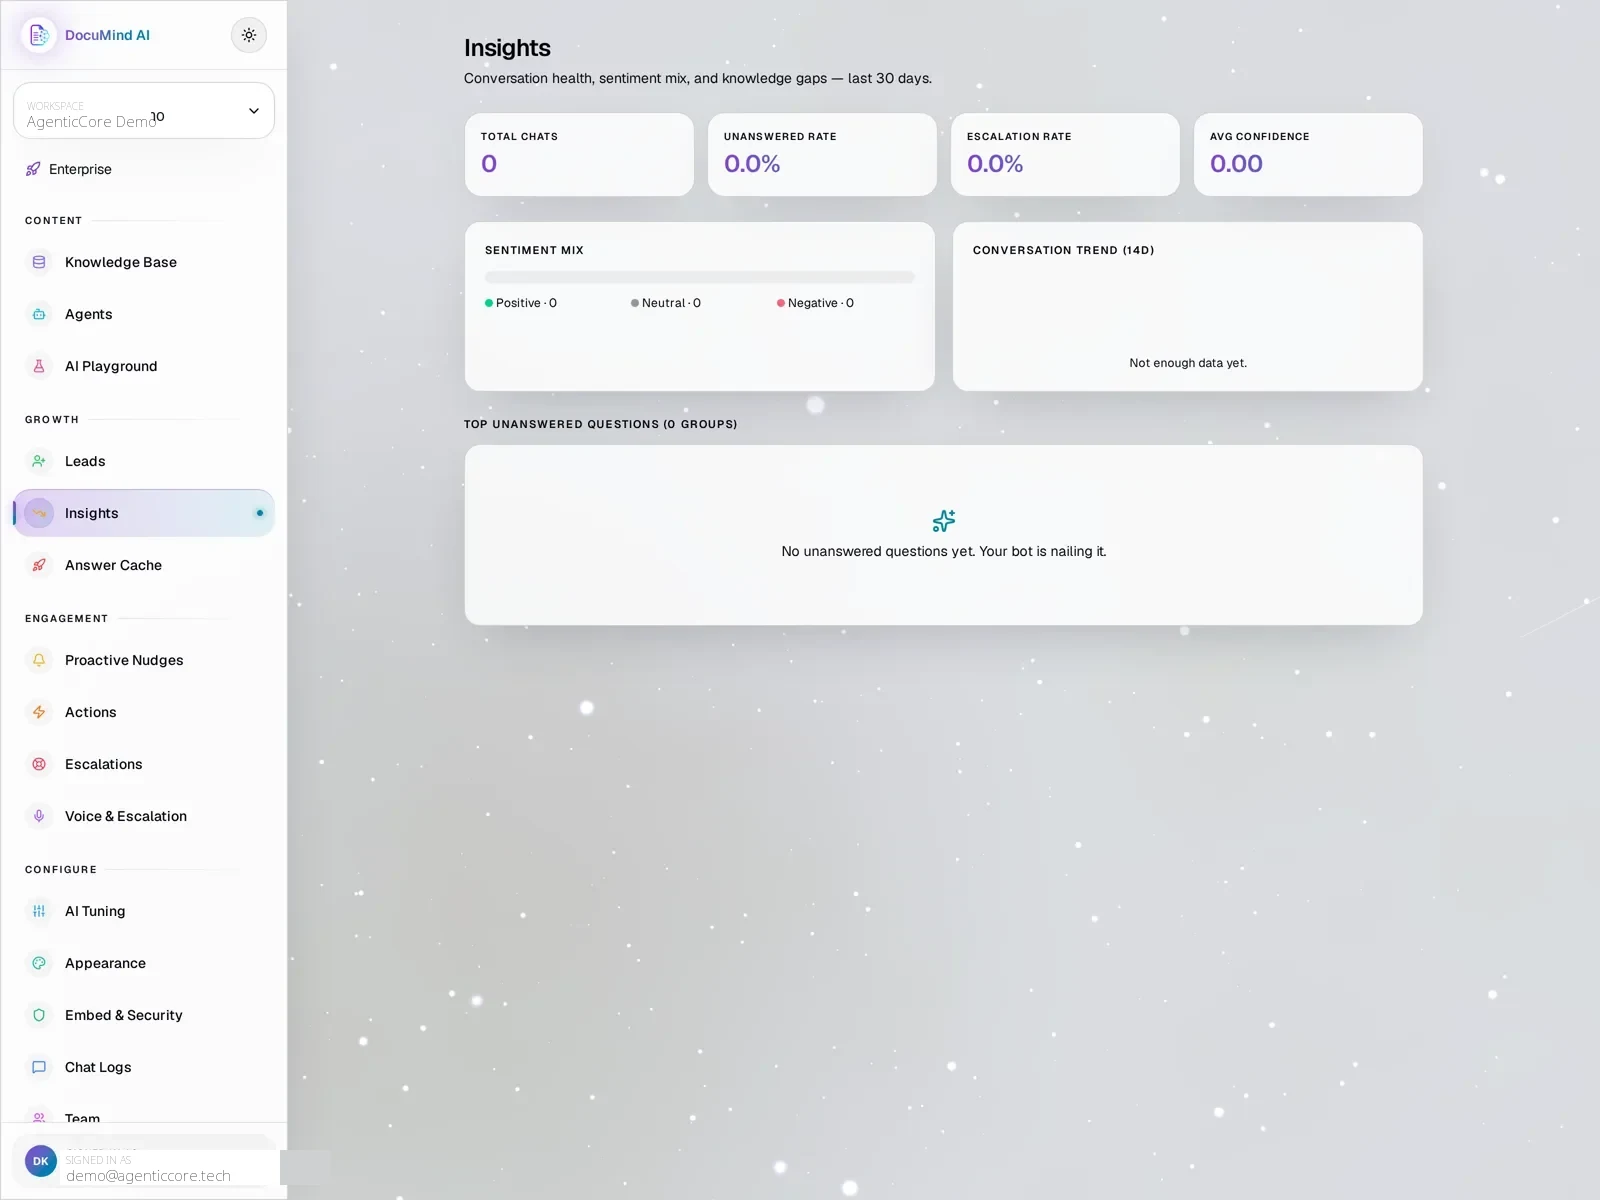
Sanitized product UI showing the monitoring surface. A live query-to-retrieval-to-citation trace and unsupported-question refusal still require a dedicated capture.
A model can answer any question about a product. The moment the answer touches pricing, security posture, contract wording or a migration step, a confident paragraph with no source behind it is a liability rather than a feature.
“The model was never the hard part. Retrieval quality and evidence were.”
Every stage exists because a specific failure showed up without it. Parsing decides what the system can ever know. Chunking decides what retrieval can find. Reranking decides what the model actually reads. Citation decides whether a reader can disagree with the answer.
Shown: source ingestion and evaluation entry points—not a fabricated retrieval trace.
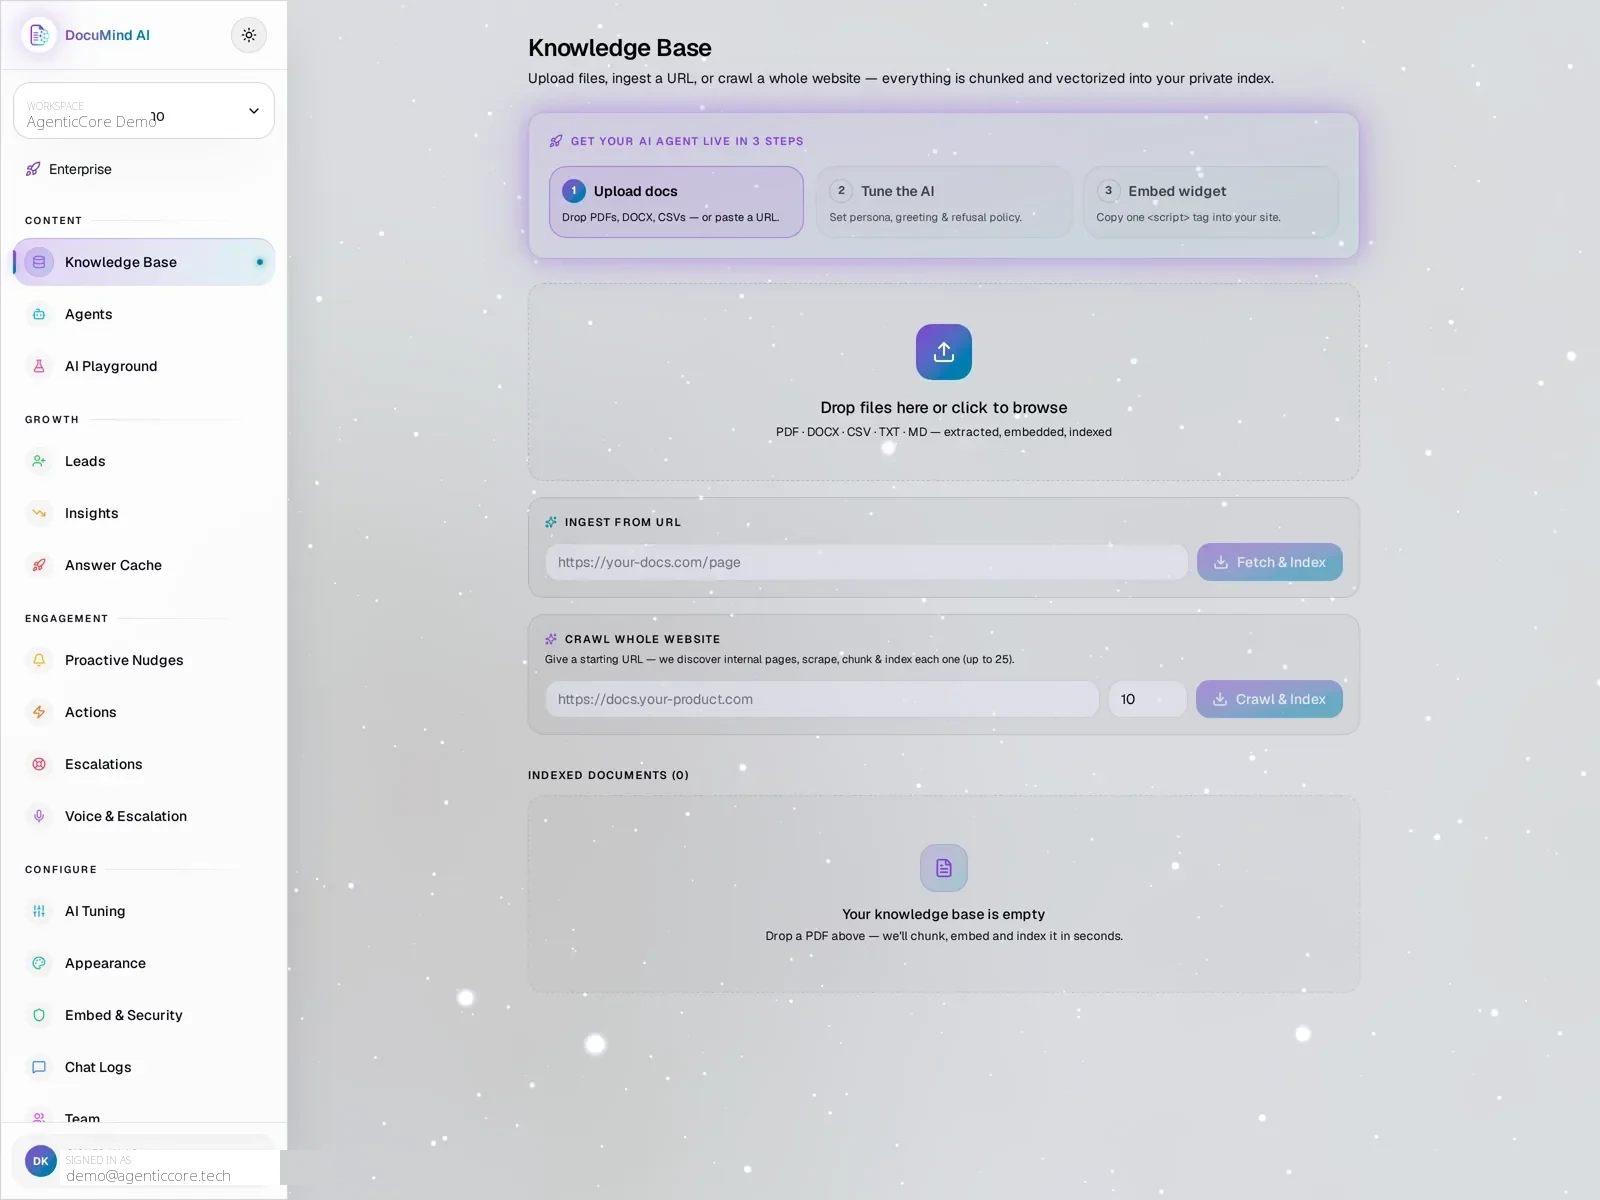
Shows the sanitized source-ingestion surface. A live query, retrieved chunks, scores and clickable source passage still require a dedicated demo capture.
Explains the identifier chain the implementation preserves. It is an architecture diagram, not a product-output screenshot.
Asking a model to “add sources” produces plausible-looking references. Trustworthy citations come from carrying identifiers through the whole pipeline: the chunk that was retrieved, the document and section it belongs to, and the position a reader can open.
In a multi-tenant knowledge system, a leak does not need a bug in the model. It only needs an unfiltered similarity search. DocuMind’s architecture places scope checks in deterministic code before retrieval and at the database boundary, so prompt text is never treated as access authority.
Most bad answers are retrieval failures wearing a generation costume. Evaluation therefore starts one layer down: given a question, did the passage that contains the answer appear in the candidate set, and did reranking move it near the top?
Shows where confidence, unanswered questions and escalation are monitored. This empty sanitized state does not claim measured production performance.
“If a wrong answer cannot be traced back to a passage, you cannot fix the cause of it.”
Every choice here buys something and gives something up. Naming the cost is part of the engineering.
DocuMind AI is my own product, built to prove out an approach. It has not been run as a client deployment, so I do not publish adoption, revenue or customer-scale numbers for it.
The work is not making a model sound certain. It is making the path from source to answer short enough that a reader can walk it themselves, and honest enough that the system admits when the sources do not answer the question.
A bounded AI workflow: structured extraction, deterministic rules and human handoff.
A bounded AI workflow for qualification and handoff
Conversation creates unstructured intent. LeadCore AI turns it into structured fields, keeps permissions, validation and limits in deterministic code, and hands off to a human when the decision is consequential. It is my own product, built as engineering proof — not a client deployment.
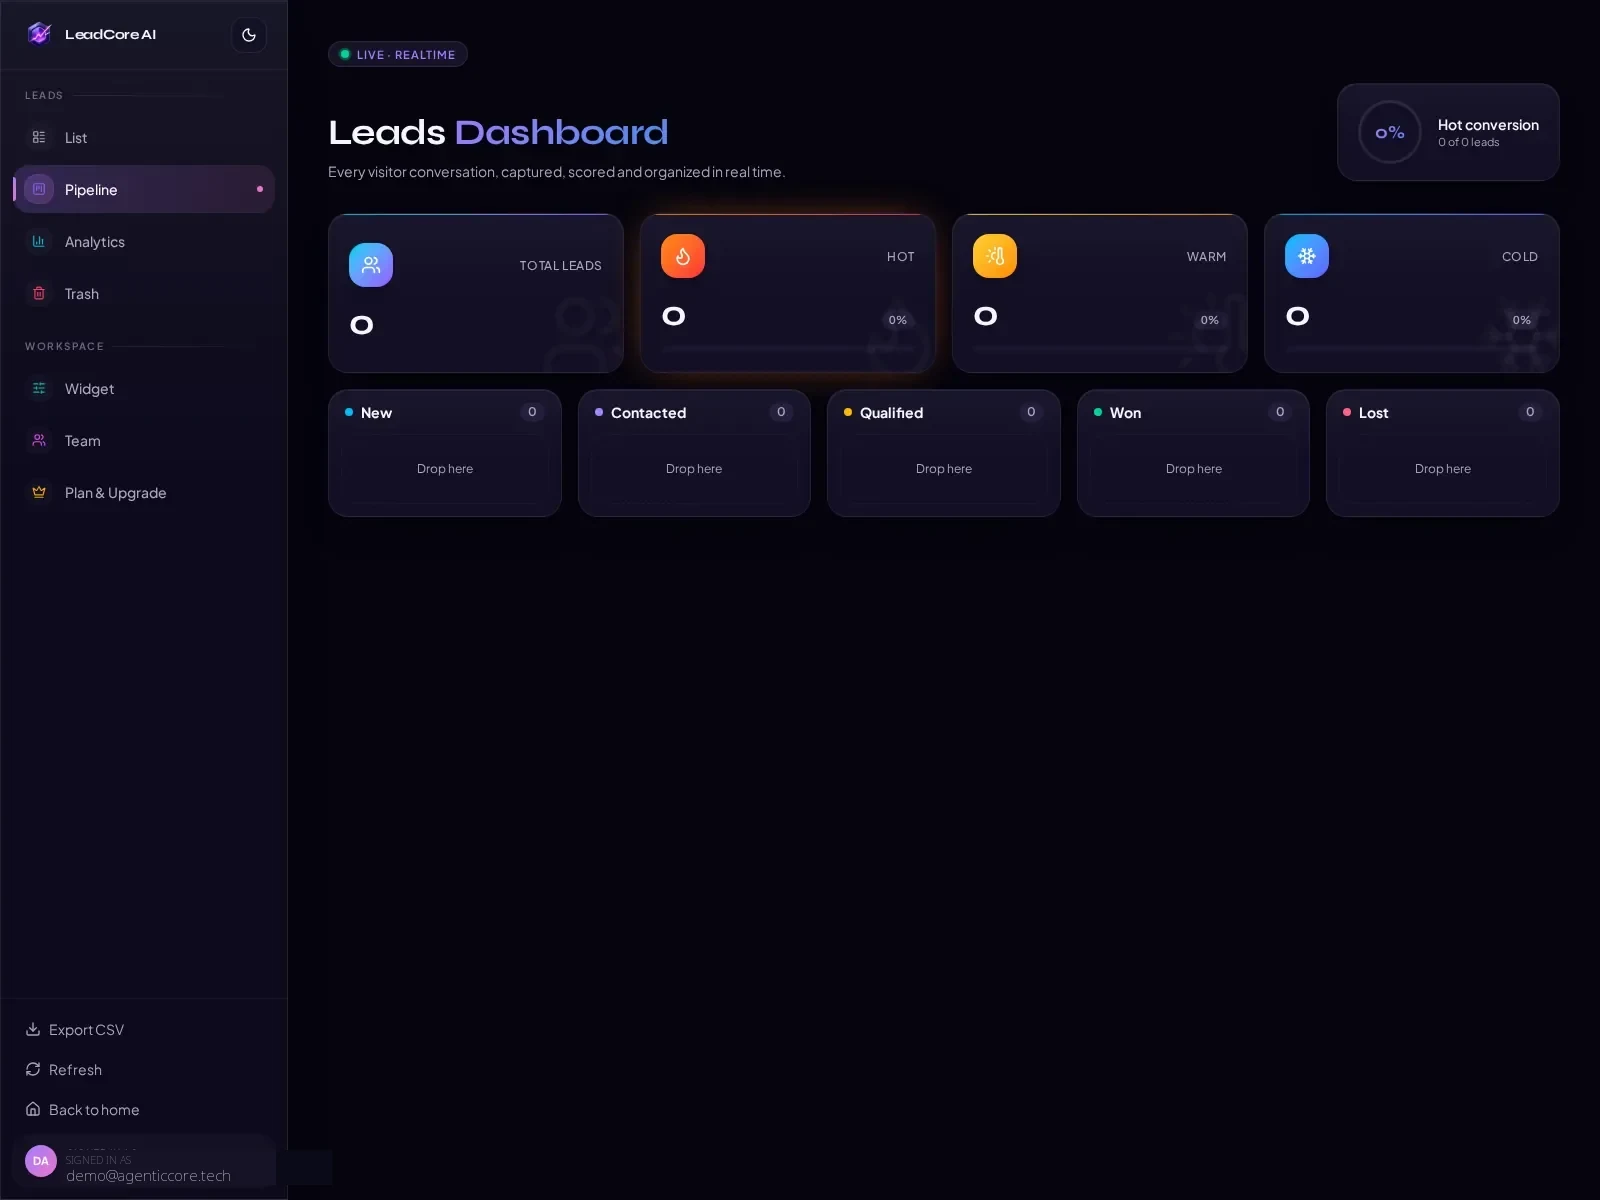
Sanitized product UI showing the pipeline surface. A populated input-to-extraction-to-rule-to-handoff trace, including uncertainty and its audit event, still requires a dedicated capture.
Qualification conversations end with a decision: route this, price this, escalate this, ignore this. The moment a model is allowed to make that decision on its own, every ambiguous sentence becomes a business risk.
The model has exactly one job in this system: read what a person wrote and propose values for a defined schema. Anything it returns is parsed and validated before the rest of the workflow is allowed to see it.
Shown: sanitized pipeline and lead surfaces—not a fabricated populated extraction trace.
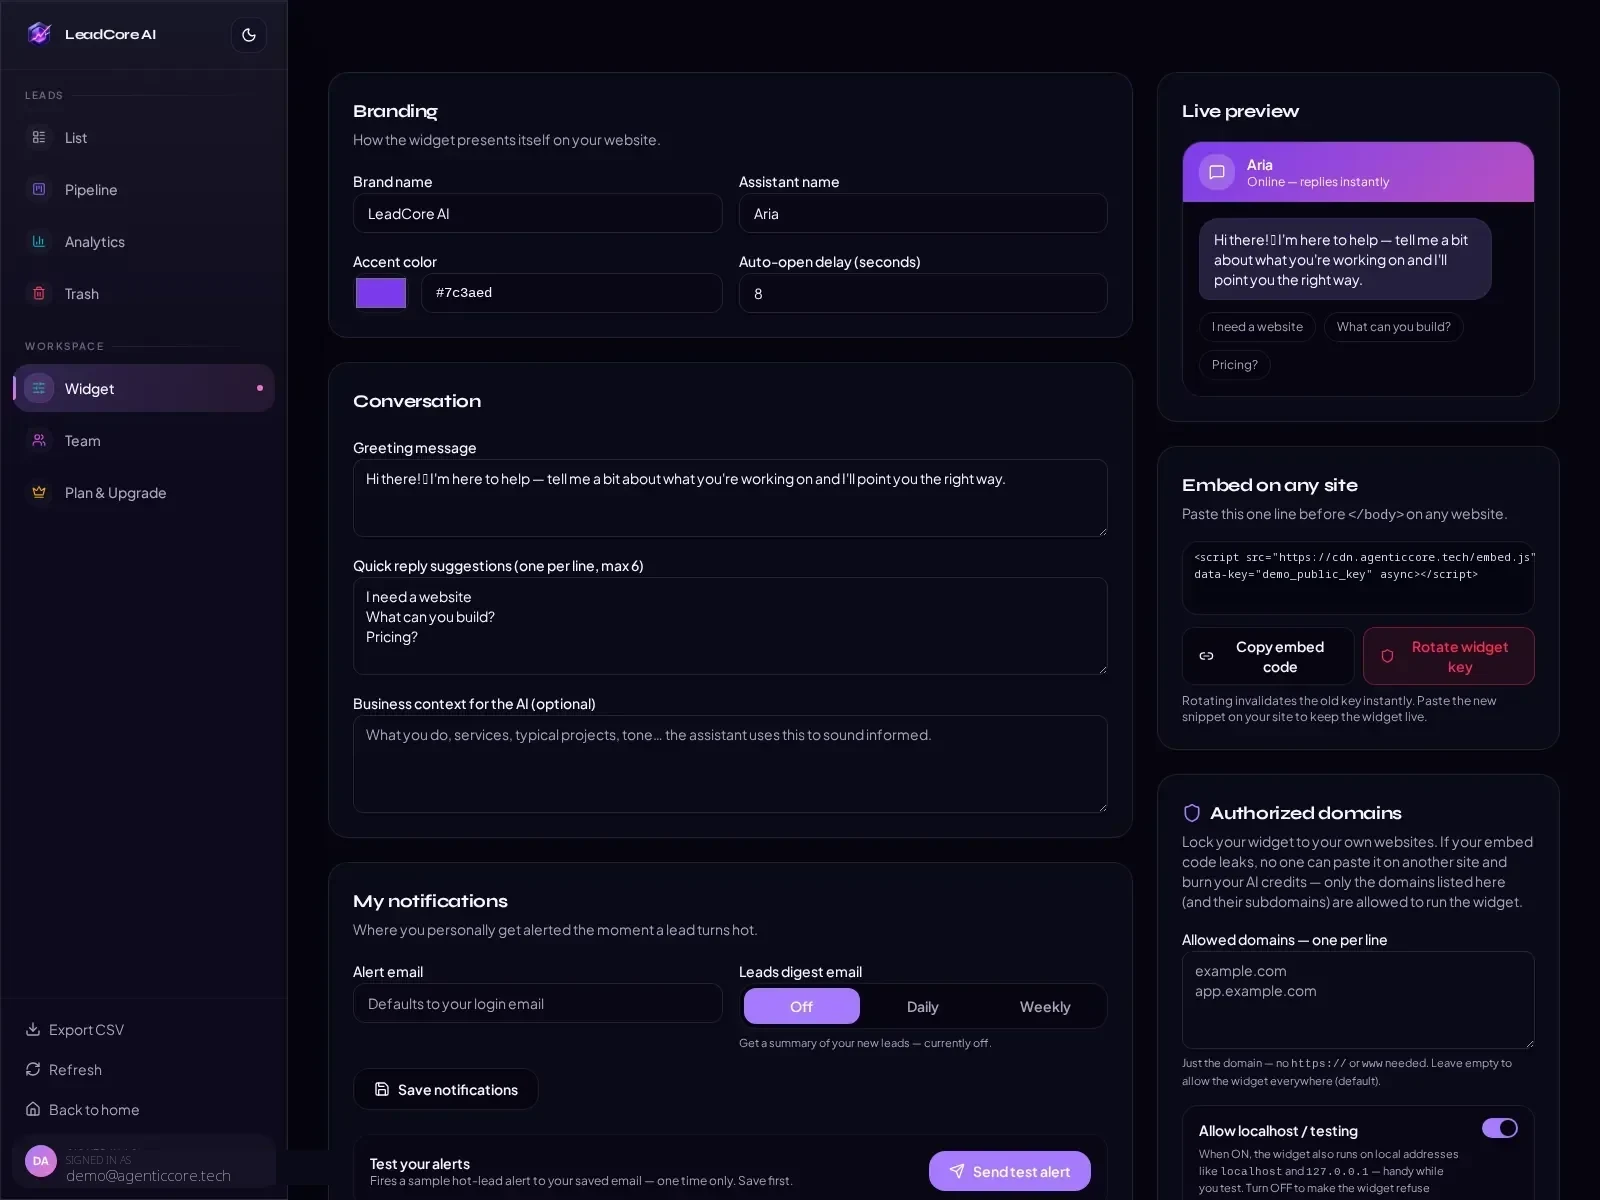
Shows the sanitized widget and conversation configuration. It does not by itself show extracted fields or schema validation.
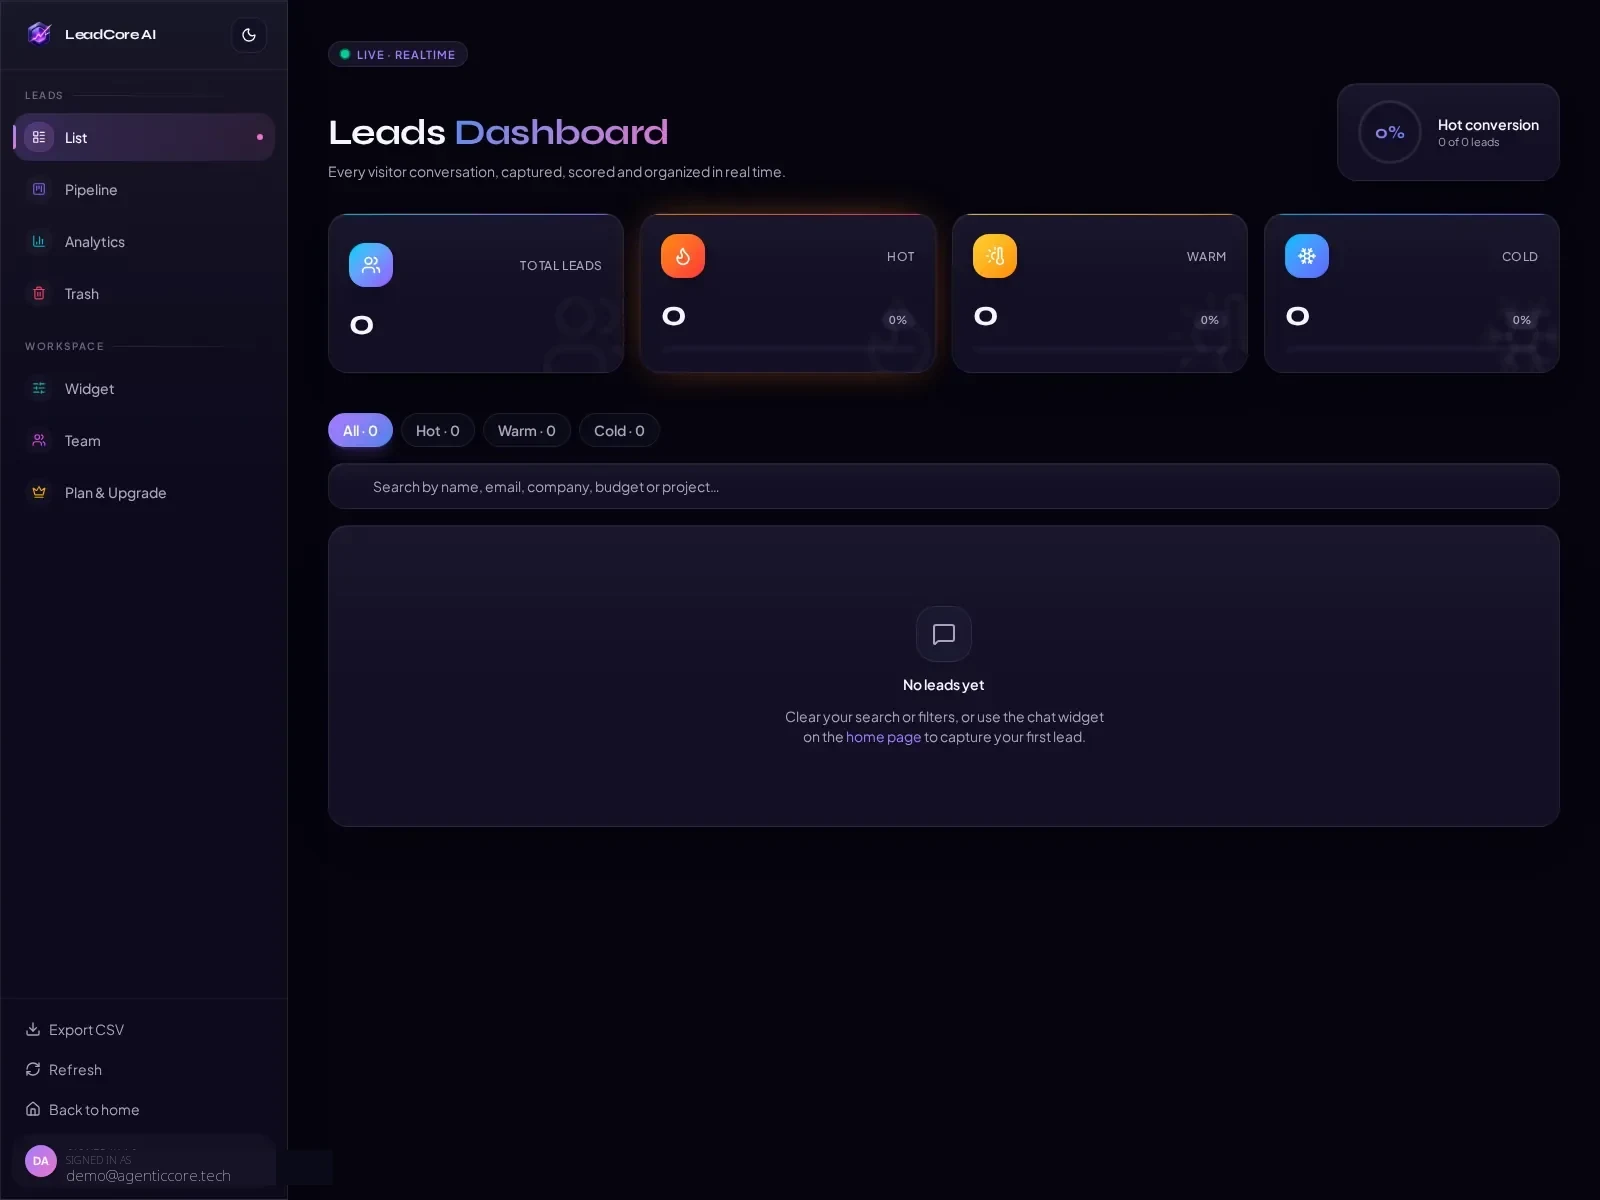
Shows the operator-facing lead surface. A populated extraction, rule result, escalation reason and audit event still require a dedicated demo capture.
The design question was never how clever the assistant could be. It was which decisions it is allowed to make at all.
Interpretation is probabilistic and belongs to the model. Decisions are business rules and belong in code that can be read, tested and audited. Keeping that line explicit is what makes the system safe to run unattended.
The workflow is designed to stop. When required fields are missing, confidence is low, a rule conflicts or the request falls outside the defined scope, the conversation moves to a review queue with everything a person needs to finish it.
Most of the engineering in a workflow like this sits around the model call, not inside it.
“A workflow that knows when to stop is worth more than one that always answers.”
LeadCore AI is my own product, built to prove out a bounded approach to AI workflows. It has not been run as a client deployment, so there are no customer results to report.
Let the model interpret language. Keep decisions, permissions and limits in code you can test. Escalate the rest to a person with the context already assembled. That is what makes this kind of AI workflow suitable for production-facing use.
A production-focused RAG system: retrieval, reranking, citations and evaluation.
SERVICES
RAG systems first, supported by the production engineering they depend on.
01 · Primary
Product and internal knowledge turned into source-backed AI answers, with retrieval, citations, refusal behaviour and evaluation before rollout.
Proof — DocuMind AI
Read more →02 · Foundation
The production layer beneath knowledge systems: multi-tenancy, evaluation, queues, observability, deployment, security boundaries and handover.
RAG & KNOWLEDGE SYSTEMS
Retrieval systems for SaaS products where answers need evidence, permissions and measurable quality.
Every claim traces back to a passage
B2B SaaS teams whose product or internal knowledge already exists, but whose AI answers cannot yet be trusted or checked.
Answers with no source. Retrieval that misses the relevant document. Knowledge that changes faster than the index. Access rules enforced in the prompt instead of the infrastructure.
Ingestion and parsing, chunking that respects document structure, similarity retrieval with reranking, grounded generation with inline citations, refusal behaviour when evidence is thin, evaluation, and tenant-scoped access.
The answer exists in your documents and needs to be located, cited and kept current.
The task is computation, a deterministic lookup, or a workflow with fixed rules. Those belong in ordinary software.
Retrieval quality, citation behaviour and failure cases are measured before a workflow becomes production-critical.
Permissions, validation and workspace isolation live in deterministic infrastructure, never in the model.
A production-focused RAG system I built as engineering proof — retrieval, citations, tenant boundaries and evaluation in one place.
Read the case study →PRIVACY
How information sent through this site is handled.
Only what you send in the contact form on this site: name, email, company, your message and the engagement details you choose to share. To prevent spam and abuse, the contact handler stores a pseudonymous network-derived rate-limit key created with secret-keyed HMAC-SHA256, your browser user-agent string separately, and the time of submission. These records are stored in this site’s project database and read by me. To deliver the enquiry notification to my inbox, the message may also be processed by the infrastructure providers that operate the contact workflow — the database host and Resend for notification email.
To reply to your enquiry and discuss possible work. Nothing is sold or shared for advertising.
There is no automatic deletion job. Enquiry correspondence is reviewed and deleted manually: messages that do not lead to work are removed once the conversation is clearly finished, and records tied to active or completed engagements are kept for the duration of that work and my own project records.
Use the contact form and write “Privacy request” in your message. You can request access, correction or deletion; I will process the request where applicable and explain any information that must be retained for legal, security or project-record purposes. Copies already handled by delivery providers may follow their own retention schedules.
TERMS
Terms for using this site.
The writing and system descriptions on this site are provided for information. They are not a warranty of any specific result.
Any work is governed by the written agreement for that engagement, not by this page.
Original writing, case-study material and project-specific assets and code on this site belong to Muhammad Daniyal unless stated otherwise. Template, third-party and open-source material remains subject to its respective rights and licenses. Project-specific intellectual property and deliverables transfer according to the signed engagement agreement.
Third-party and open-source components remain subject to their respective licenses.
Information sent through the contact form is handled only to assess and respond to the enquiry, and is not published or shared for unrelated purposes. Formal confidentiality obligations apply only when set out in a signed NDA or engagement agreement. Infrastructure providers may process the information as needed to operate the contact workflow.
Where a signed proposal or engagement agreement differs from this page, that agreement governs.
This site is provided as-is, without warranties of any kind, including for the accuracy of its content.